
One runtime for ingestion, transformation and quality
Schedule all three on the same platform, including the sources your GUI tool has no connector for. The orchestrator you were about to stand up is one you no longer need, and the one you already run keeps working.
Consolidate three tools into one runtime
Ingestion, transformation and data quality share one scheduler, including hard-to-reach sources.
Keep the orchestrator you already have
Already on Airflow or dbt? dltHub runs beside them: one Airflow task per resource, with your DAG still in charge.
Compute that runs only while your job does
Pick a machine size per job and pay only for the seconds it runs. A tuned pipeline finishes sooner and costs less.
Managed infrastructure
The sources your GUI tool has no connector for
Your agent writes the dlt pipeline that reaches them. dltHub runs it: scheduled, observable, with secrets and regions handled. One runtime covers the ingestion, the orchestration and the operations around both.
The agentic layer
Your coding agent writes the pipeline, through the AI harness and the context graph.
AI harness →operates ↓
Hard to reach
10,100+ REST API sources, plus any SQL database or filesystem


dltHub managed infrastructure
Runs your pipelines, so you don’t
Your warehouse
Wherever it already is


The pipeline stays plain Python you can read, diff and own. What changes is that you no longer run the infrastructure underneath it.
Scheduled, and deployed from your repo
Cron and event-driven triggers with follow-up chains, and a deploy that runs from the CI you already have.
Scheduling
DocsCron and event-driven triggers, with follow-up chains that wait for the loads above them.
| Job | Type | Profile | Trigger | Next Run | Last Run |
|---|---|---|---|---|---|
load_salesforce_objects crm_raw | Batch | prod | At 06:00 AMTag: extraction | in 8h 9/15/2026, 6:00:00 AM GMT+2 | 16h ago |
load_stripe_payouts finance_raw | Batch | prod | At 06:00 AMTag: extraction | in 8h 9/15/2026, 6:00:00 AM GMT+2 | 16h ago |
build_revenue_cdm finance_core | Batch | prod | After load_salesforce_objectsAfter load_stripe_payoutsTag: transformation | – | 16h ago |
CI/CD
DocsPipelines are Python in your repository. Deploy them from your own CI with a workspace API token, reviewed and merged like the rest of your code.


- ✓checkoutorders-pipeline @ 8f21c4e
- ✓dlthub profile use ciworkspace token
- ✓dlthub deployworkspace · finance
- →dlthub job runload_orders
You find out before your stakeholders do
Runs, schemas, lineage and logs on one surface, and a failure that reaches the person who owns it with the diagnosis already attached.
Observability
DocsRuns, schemas, lineage and logs on one surface, with the reason a run failed attached to it.
| Pipeline | Started | Duration | Rows | Status |
|---|---|---|---|---|
| load_salesforce_objects | 06:00 | 2m 14s | 184,220 | |
| load_stripe_payouts | 06:00 | 48s | 12,004 | |
| load_oracle_bicc | 06:01 | 6m 02s | 0 | |
| build_revenue_cdm | 06:08 | 1m 31s | 96,412 |
Alerting
DocsFailures, freshness breaches and recoveries reach Slack or email with the diagnosis attached.
| Event | Pipeline | Sent to | At | |
|---|---|---|---|---|
| Load failed | load_oracle_bicc | Slack · #data-alerts | 06:07 | |
| Freshness breached | finance_core | Email · data-oncall | 06:15 | |
| Recovered on retry | load_oracle_bicc | Slack · #data-alerts | 06:22 |
Scale out and up, in Python
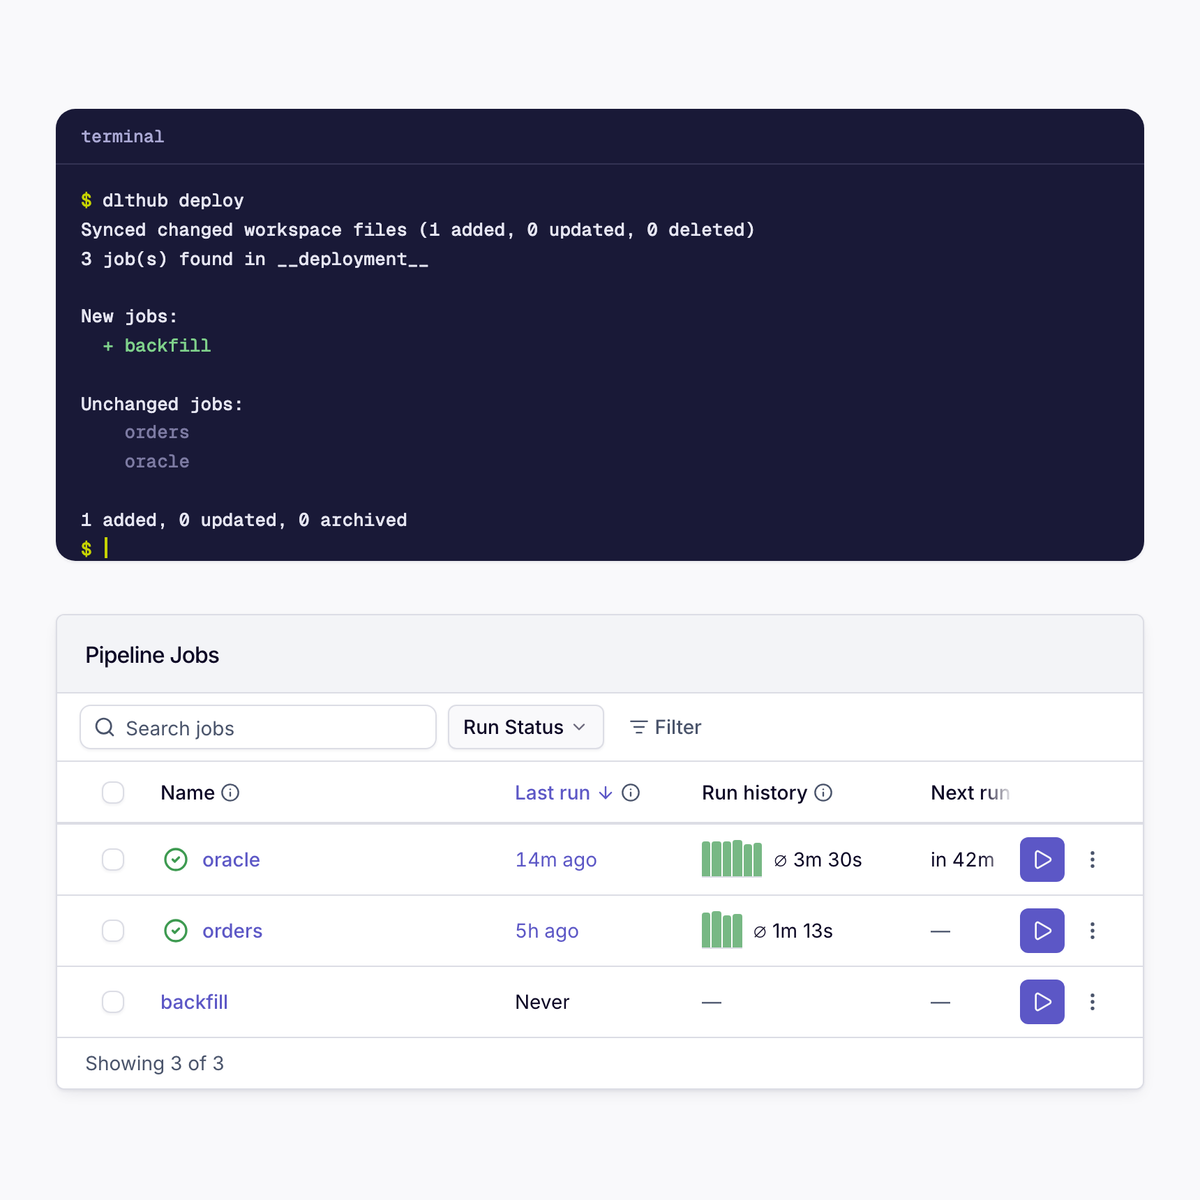
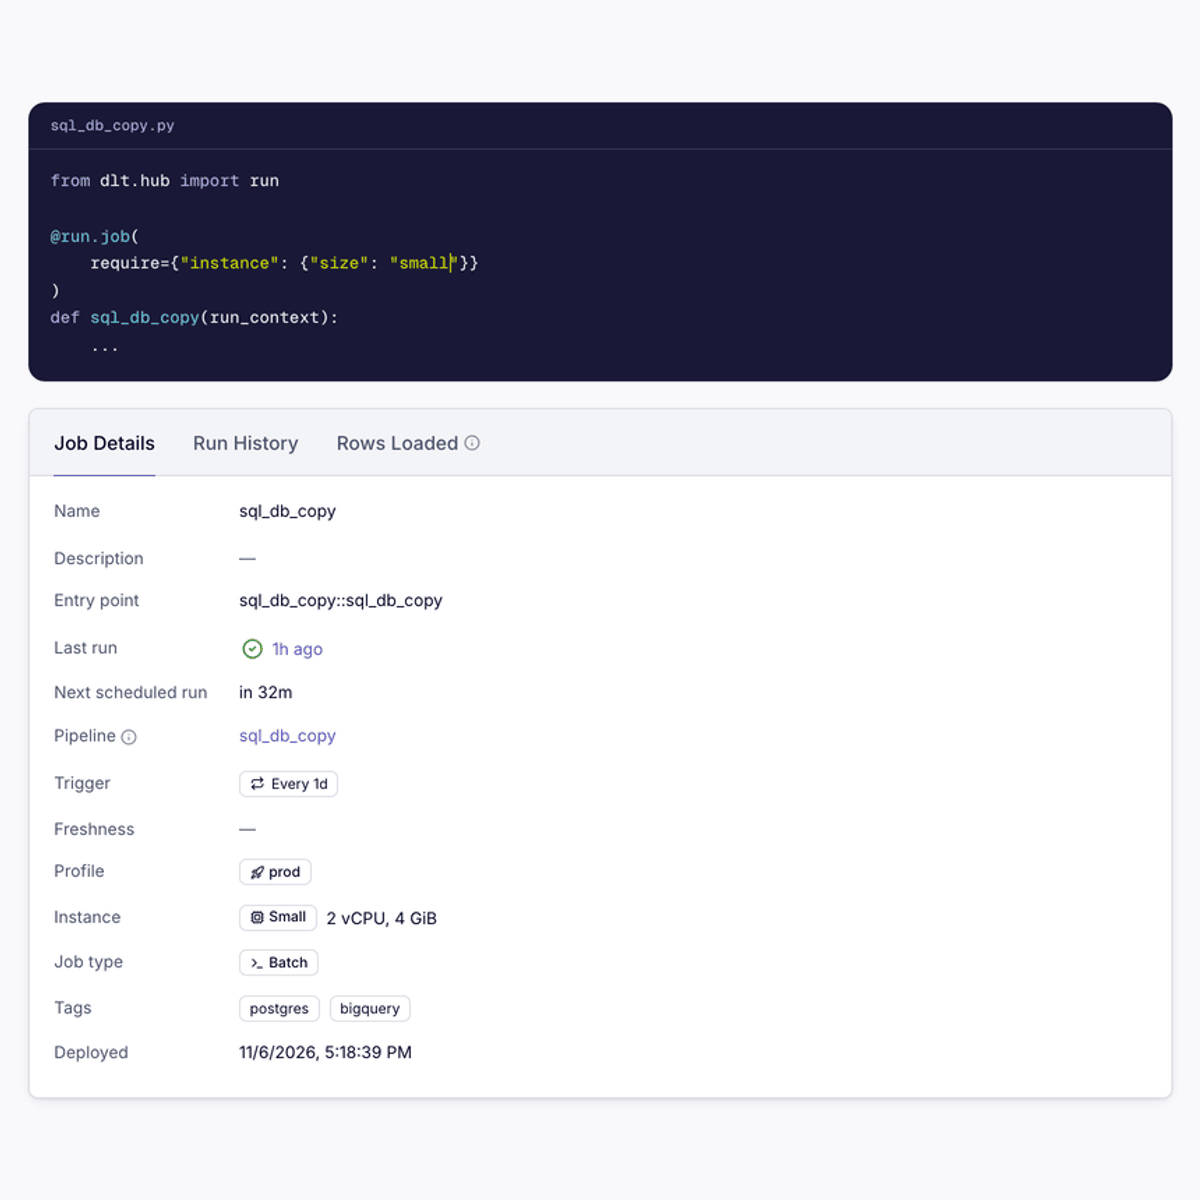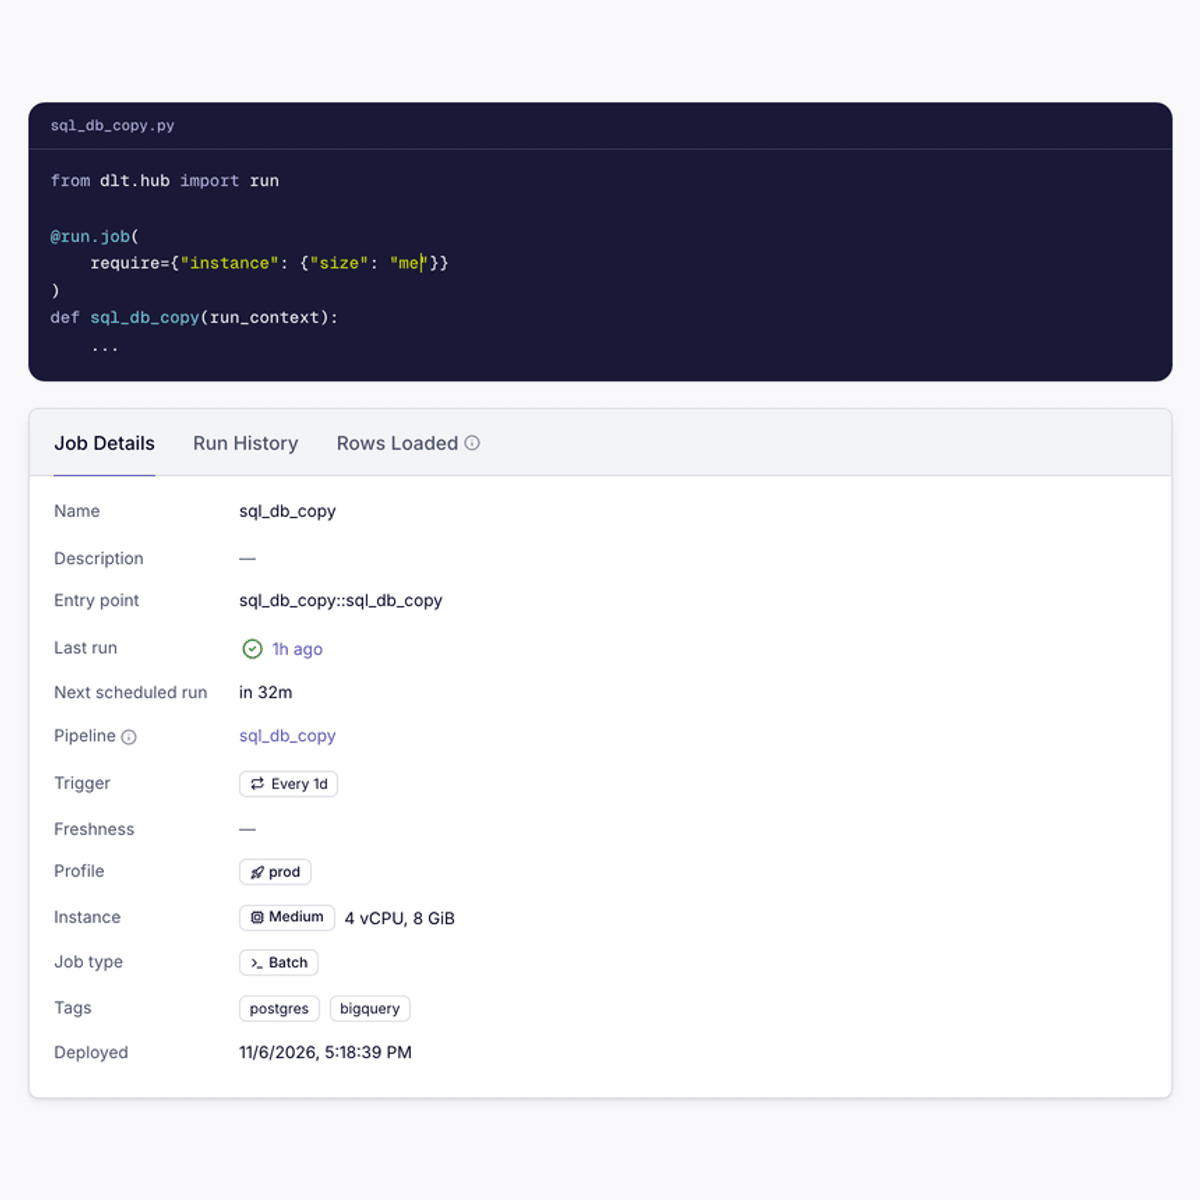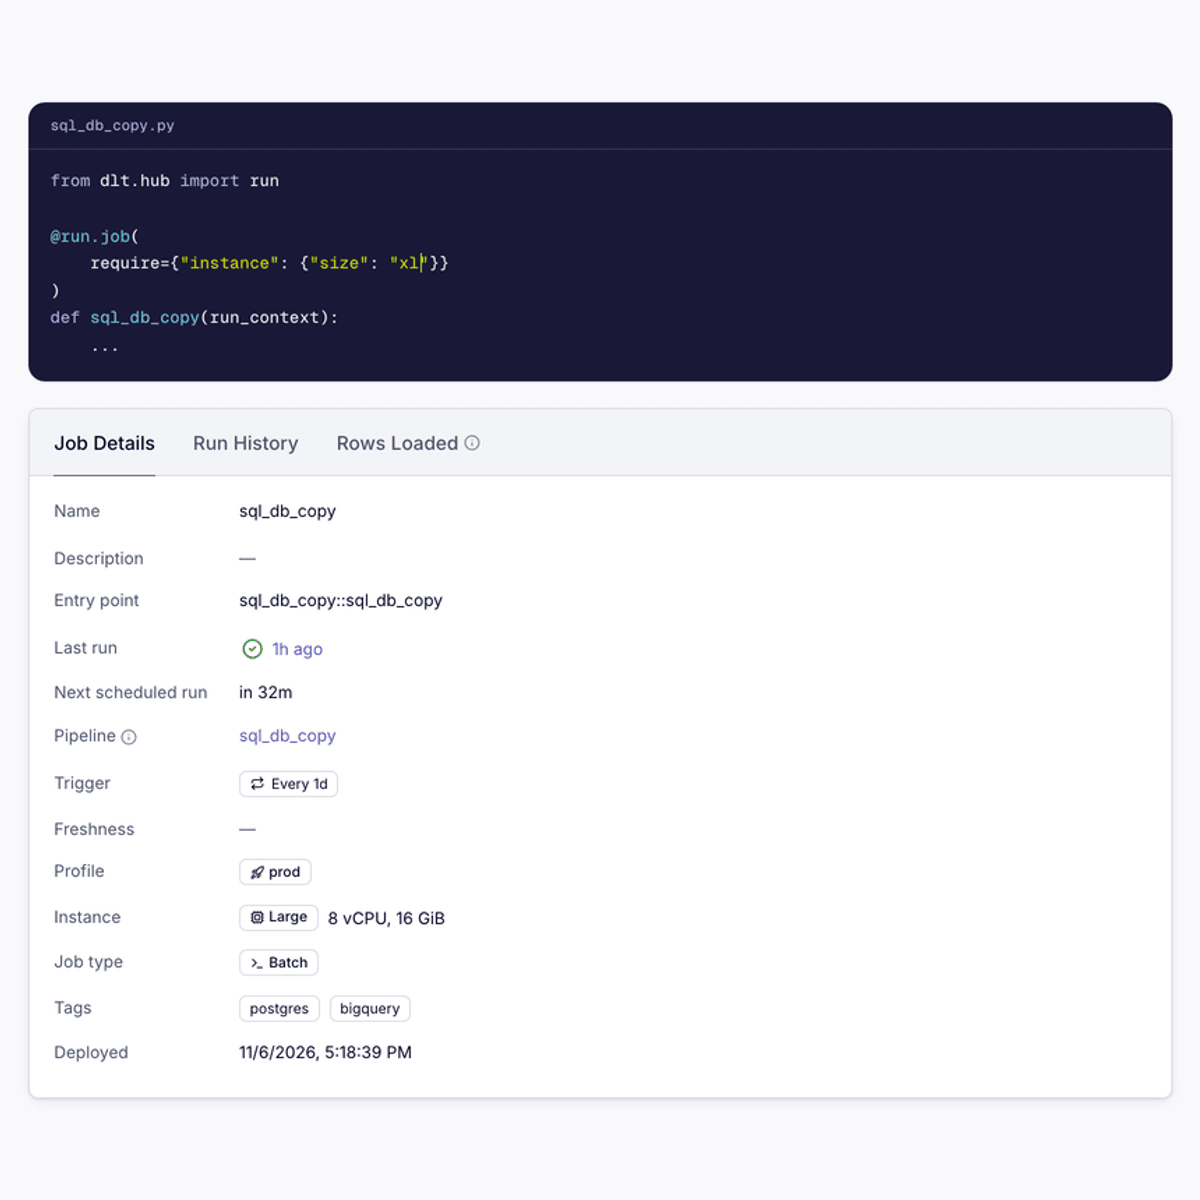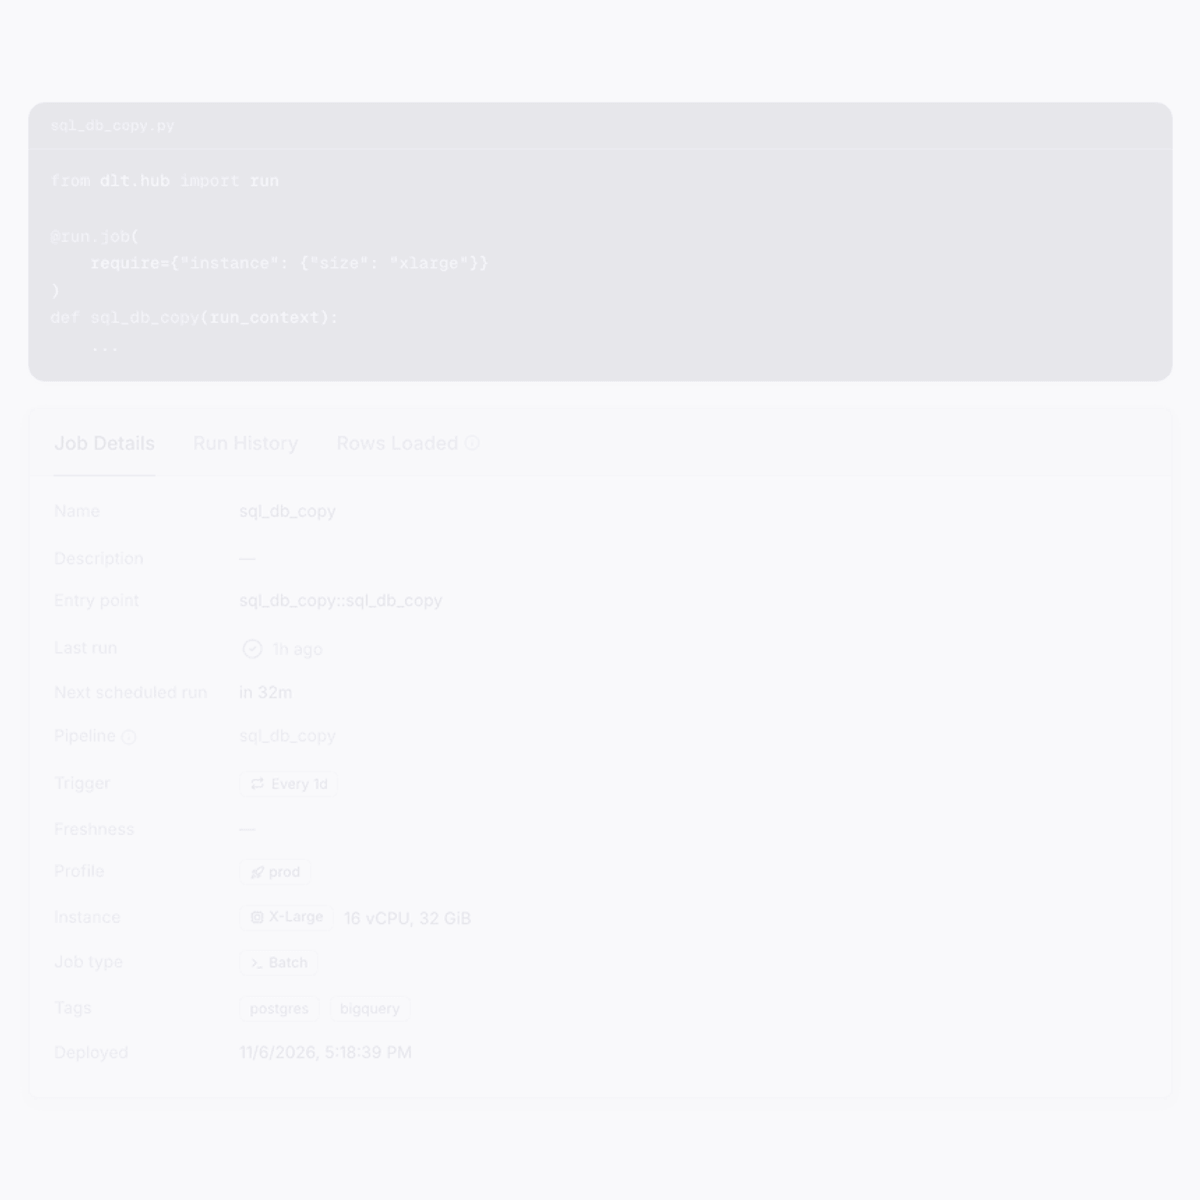
Another job scales out. One argument scales up, from small to xlarge, or extends the timeout past the 120-minute default. And when a pipeline is slow, your coding agent finds the slow stage and tunes it first.
Deployment manifest
DocsYour infrastructure is Python in the same repo. Adding a job is a function, and giving one a bigger machine is an argument. Both go through review, and `dlthub deploy` ships them.
Instance size per job
DocsSet the size in the job's code, from small (2 vCPU, 4 GiB) to xlarge (16 vCPU, 32 GiB), and it shows on the job's details page. Larger sizes use your budget faster.
Performance toolkit
DocsSkills that profile a slow pipeline and name the change that makes it fast, with a playbook per source type: REST, SQL and filesystem.
- Serial extractionParallelise 8 resources4.1x
- Full refresh each runAdd incremental cursor9.7x
- Batch size 500Raise to 50,0002.3x
Drive it from your own tooling
The CLI ships today and is how most people drive the platform. The API and SDK are in private preview, for teams that want to trigger and monitor runs from Airflow, dbt or their own scheduler.
CLI
DocsRun, inspect and debug from your terminal, with the same commands your CI uses. No dashboard round trip to find out what a pipeline did.
dlthub job logs load_orders -f
06:01:12INFOextract oracle_bicc 14 resources
06:01:48INFOnormalize 184,220 rows
06:02:31WARNschema amount: int -> decimal
06:03:04INFOload snowflake 184,220 rows
06:03:04INFOdone 33s
API and SDKPreview
DocsTrigger and monitor runs from Airflow, dbt or your own scheduler, with a workspace token. In private preview, so ask us for access.
- POST/v1/jobs/{id}/runsTrigger a run
- GET/v1/runs/{id}Poll status and rows
- GET/v1/workspaces/{id}/runsList recent runs
- PUT/v1/secrets/{key}Rotate a credential
Skills to run pipelines on dltHub
Two of the ten toolkits in the dltHub AI harness. Their skills deploy, schedule and recover pipelines, and find out why a pipeline is slow or running out of memory, then fix it.
Called from
dltHub Platform
Managed infrastructure for Day 2: runs, schedules, recovery
Verify the dlthub workspace is ready for dltHub Platform. Use when deploying for the first time, or when another skill reports missing prerequisites.
Performance
Find the slow stage and tune extract, normalize, and load
Make a pipeline faster or lighter on memory. Diagnose the bottleneck stage, then apply parallelism, workers, buffers, or batching.
Paste this into your coding agent
Installs the harness if it is not already set up, then runs the skill.
I want this pipeline running on a schedule in dltHub Platform. Is my workspace ready?
Explore the rest of dltHub
Transformations
Annotate your sources, generate the canonical model, and keep your dbt models running.
See the modelsData quality
Expectations, schema contracts and PII redaction, running on the way into the warehouse.
See the checksAI harness
The skills, commands and MCP servers your coding agent calls to build and fix pipelines.
See the harnessSecurity and compliance
Access controls, credential handling, encryption, data residency and audit, with the control set published.
See the controlsPricing
Pick a machine size per job and pay by the second, with the meter running only while the job does.
See pricing


