
Towards a Self-Improving Autonomous Data Platform
A data platform should run like a power grid: routine faults cleared automatically inside a bounded scope, anything risky escalated to a person. This is the four-level autonomy ladder dltHub is climbing, and the context graph that makes each step safe to take.
 Elisabeth Reitmayr,
Director of Engineering
It's Monday morning, you sit in a cafe and open your laptop. Your data systems health monitor is green. Overnight, an upstream API changed a column type and a load failed at 2am. Nobody got paged. Your pipeline health agent recognized the failure as familiar, applied the pre-authorized fix, reran the load, checked that the data landed, and left a message on Slack:
The 02:04 load ofbilling.invoicesfailed: the source API now sendstotal_amountas a decimal. I applied the pre-authorized fix (5th time on this pipeline) and reran the load; all 40k rows landed, counts match the source.
You read the note with your first coffee and mark the fix as good which feeds the agent's track record - the same record that earned it the permission to act that night without waiting for you. Then you turn to the decisions that actually need you: approving an agent-proposed backfill with a wide blast radius, promoting two fix types to pre-authorized after weeks of clean runs, and briefing a coding agent on the pipeline you decided to add.
Later that morning the CFO of your company pings you, excited, with a question: can these numbers be trusted? Last week the payment provider started sending a fee breakdown on every transaction. The platform picked up the new columns on its own and flagged them as worth modelling, and an insights agent alerted the finance team this morning: cross-border card fees are eating about a point of margin on European orders, and most of that volume could settle through local acquiring. The CFO has already dispatched an agent for a breakdown by payment method. Before Finance changes the routing, they want your sign-off on the data. You reply with a link to the lineage and checks and order the next coffee.
That Monday morning shows a data platform running like automated infrastructure, the way a power grid runs: routine, pre-authorized faults are cleared automatically within a bounded scope, anything persistent or high-risk escalates, and the people in the control room spend their time on the decisions that need a person. The rest of this post describes how dltHub is evolving into that kind of platform: an autonomous and self-improving data platform that earns more autonomy over time, decreasing the cost of operations and maintenance while remaining secure and transparent.
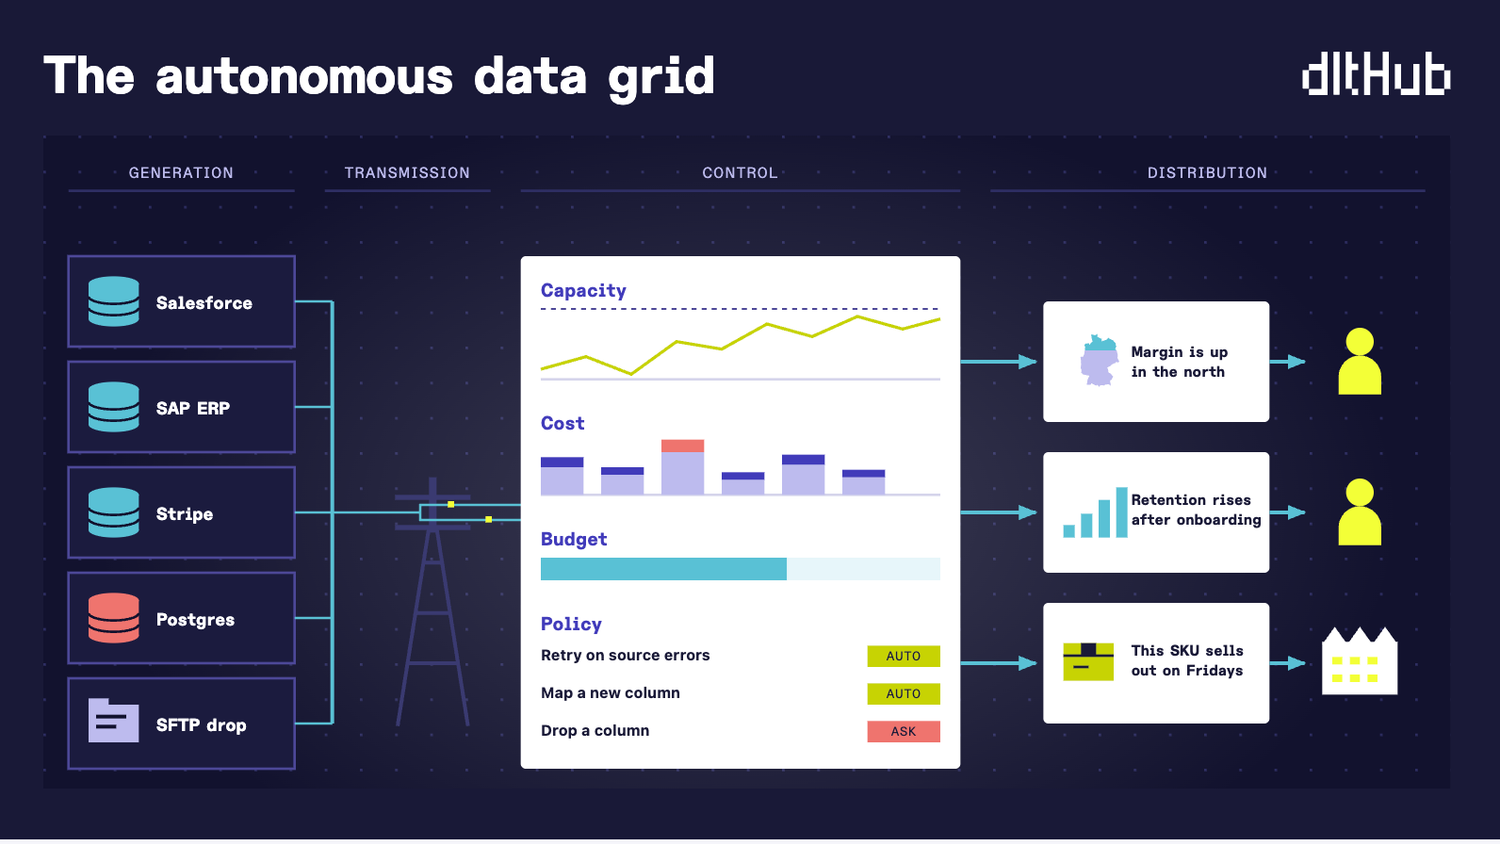
The autonomous data grid
A data platform is infrastructure in the same sense as the automated energy grid: a company depends on it the way it depends on power, continuously and mostly without noticing it. Automation in that kind of infrastructure is decades old, and the rules for it are well worked out.
A power grid is heavily automated and still fully supervised. When a branch falls on a power line, the power usually comes back a few seconds later: a switch on the pole turned the line off and on again, without asking anyone. If the problem is still there after trying another time, the switch leaves the line off and a person gets called. Engineers decide in advance which problems the equipment may handle on its own, with every action constrained by safety rules, recorded, and reversible where possible.
We want that degree of automation for data, and we want to be able to see all of it - without having to look into all of it. A control room has a live picture of the whole network: every line, every switch, what is loaded and what is off. Operators work from the monitors in their control room rather than from the wires. With dltHub, we build automation and observability hand in hand: agents keep the network running, and our context graph brings transparency in all areas. Every action is visible, explained, and auditable, and the autonomous agents can always show what they did and why. That makes the autonomy safe to deploy in the first place.
The dltHub autonomy ladder
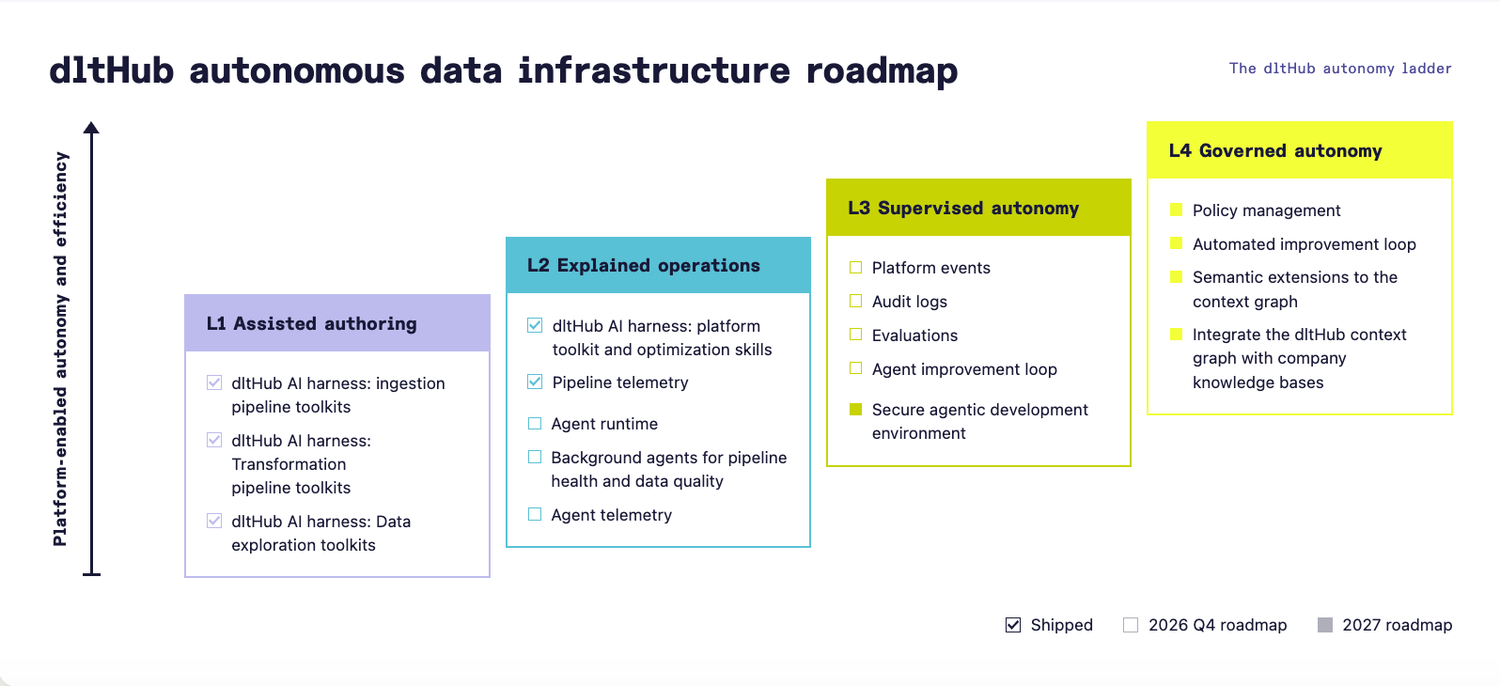
Getting to that automated grid is a climb. We think about it as a ladder with four levels, with platform autonomy and operational efficiency increasing with each step:
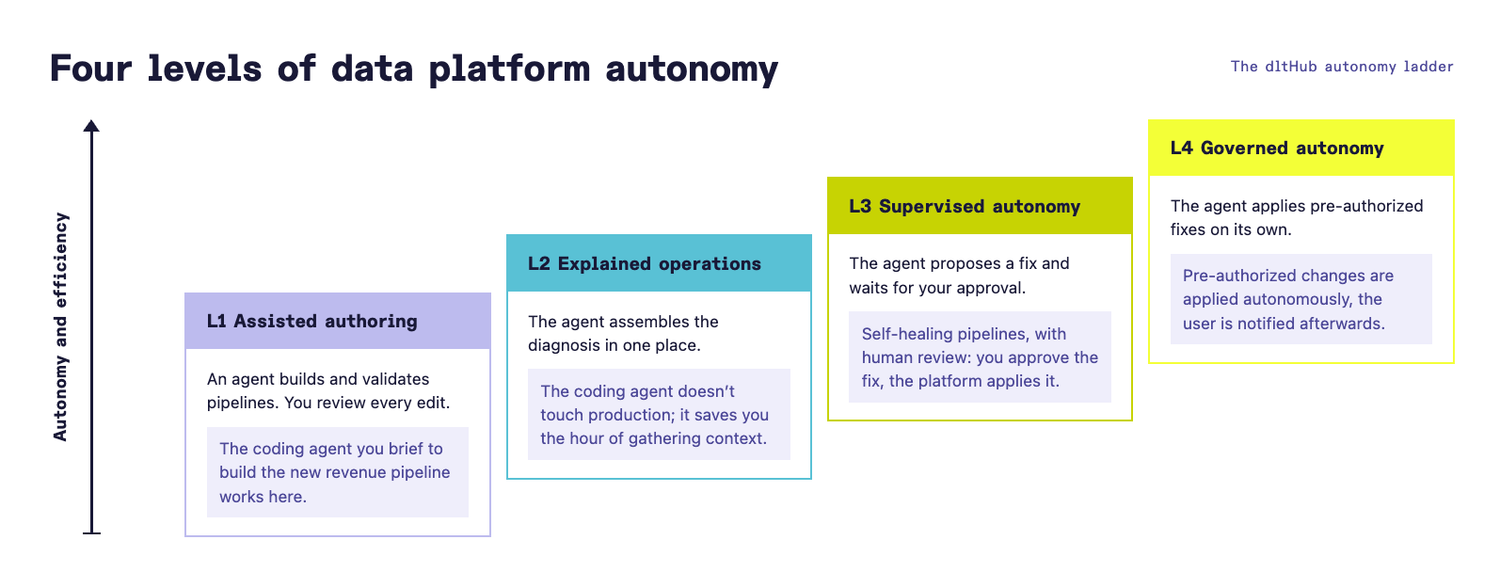
Humans stay at every level but their involvement changes: instructing agents on how to fix a new kind of logic bug, judging whether the data is semantically right, deciding a change's risk tier, and setting the autonomy policy.
Rating the risk of an activity has a high impact, because Levels 3 and 4 runs on risk tiers. A risk tier rates a proposed change on two questions: how much can it break (rows and tables touched, downstream consumers, SLA impact), and how hard is it to undo (whether it rolls back, and how fast). A retry is in the lowest tier - it touches nothing new and reverses itself. It follows the switch on the pole: two attempts, then escalation rather than another try. A backfill that rewrites a year of a revenue table sits higher, even when the fix is one line. Low tiers are eligible to become pre-authorized changes that agents can apply autonomously. High tiers always involve a person. A specific list stays off limits at every level, similar to a grid not letting automation rewire the network on its own. For data infrastructure these are for example: deleting data, schema changes that break a downstream contract, reading sensitive data.
Guardrails like these are prerequisites for the levels - each step up the ladder has to be earned with new infrastructure before it is safe to take:
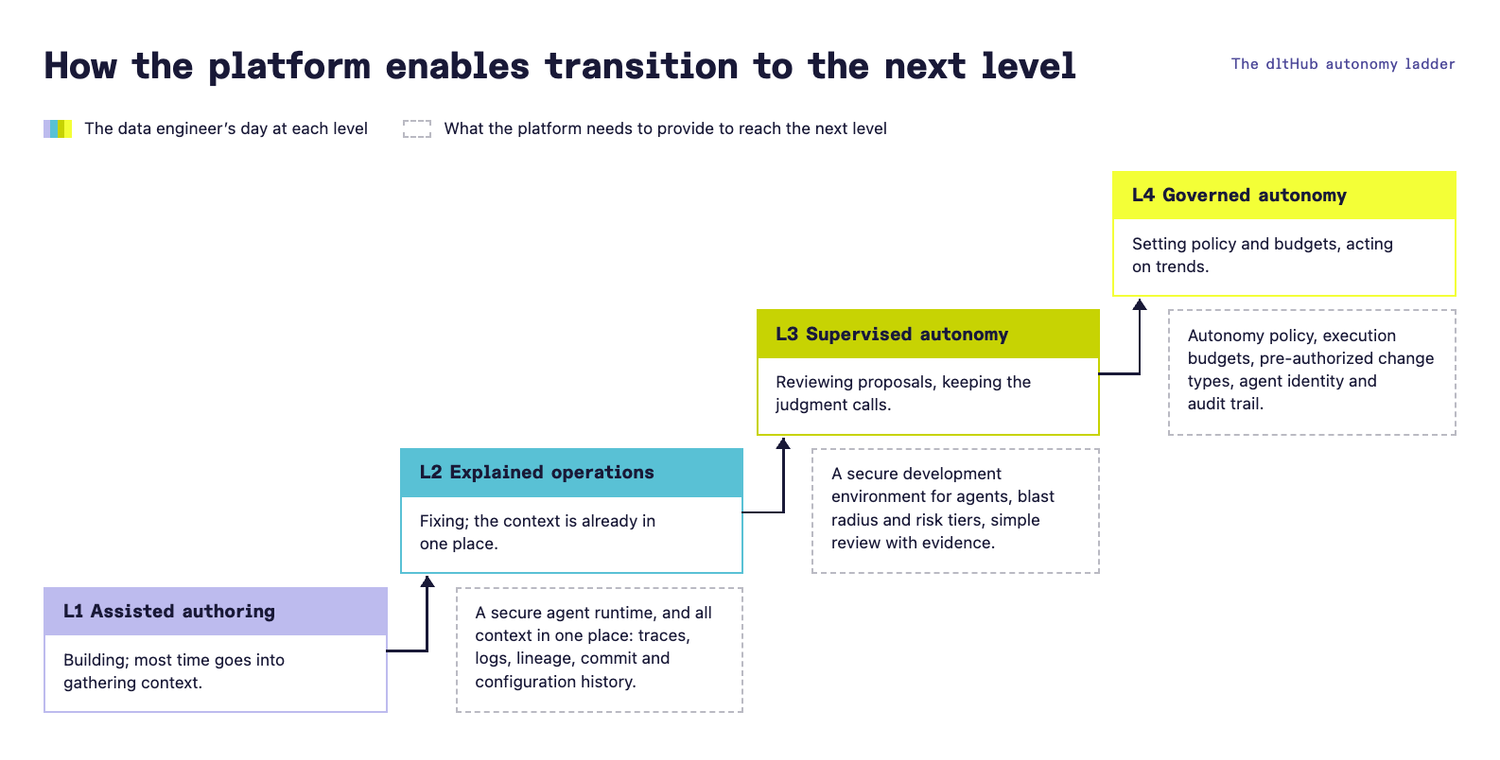
Not every activity should climb to the top. Pipeline repair can reach L4, but only for failures it has seen before. Dataset repair, where the pipeline runs green and the data is still wrong, stays at L3 in many cases because deciding data is wrong most of the times involves a judgment call.
The feasibility of autonomous repair also depends on the quality of the pipeline code. dltHub pipelines declarative and lean because the library already handles the parts that usually go wrong: incremental loading, retries, schema evolution, load state, and typed normalization of deeply nested data. What is left in the code is the part that is specific to the source, which is also the part an agent has to reason about when it diagnoses a failure or applies a fix. dltHub enables this for any source, from a legacy systems with undocumented APIs to highly nested traces coming out of your agent runs. A few thousand lines of bespoke extraction logic with hand-rolled retry and state handling is a far worse starting point at every level of the ladder.
How working with data changes at each level
The Monday morning in the introduction is what L4 looks like, but this is not the starting point. Trust in an agent grows similarly to how trust in a new team member does: you stay close at the beginning, and you hand over more as the work keeps holding up. With one new colleague that judgment can comfortably live in your head; with agents acting at machine speed across hundreds of pipelines, it has to be written down, as policy and a track record the platform keeps for you. Power grids went through the same evolution: automation arrived one substation at a time, and every new device ran under supervision until it had proved itself.
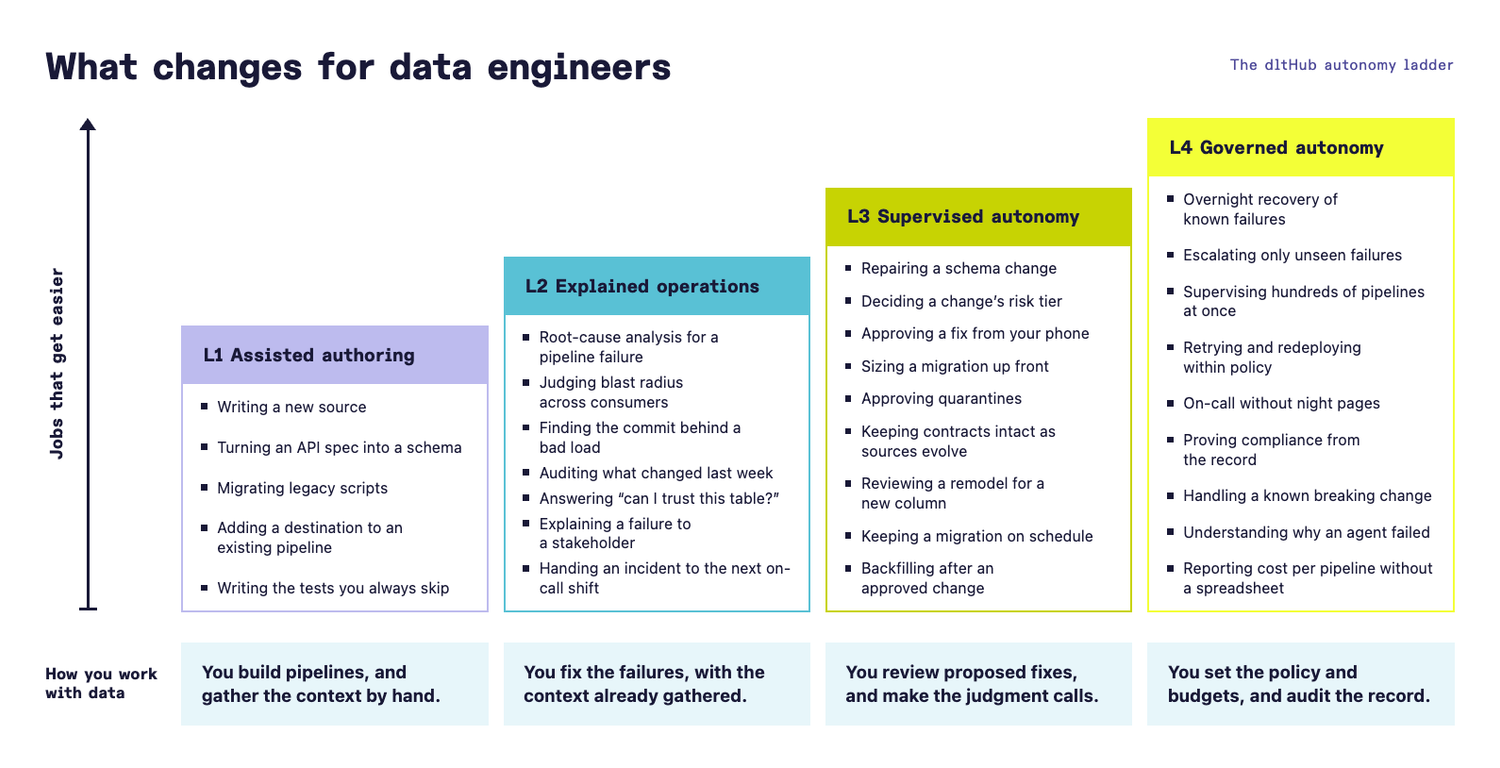
For data engineers, climbing the ladder shifts the role from coding to supervising. The quality risk shifts too. At the lower levels the danger is alert fatigue: you receive so many alerts that you stop reading them. At the higher levels it is rubber-stamping: approving agent proposals without really checking them. To avoid this, every proposal contains easily digestible evidence: the diagnosis, the blast radius, and the track record. When a reviewer can see at a glance why a change is safe, actually reviewing stays cheaper than blindly approving and dealing with the undesired consequences.
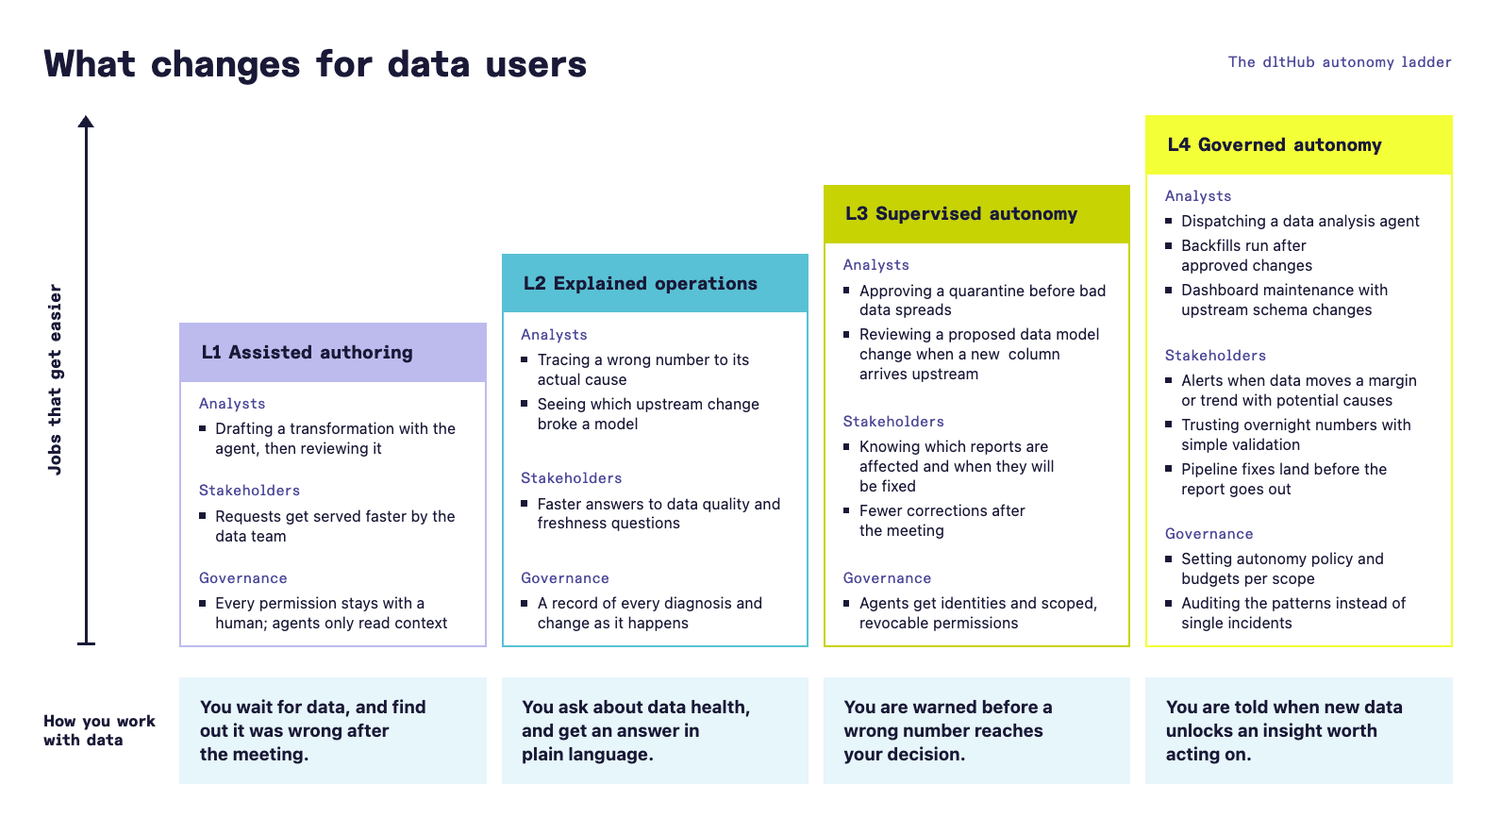
Climbing the ladder also changes the job for the people who consume the data. An analyst moves from finding out after the meeting that a number was wrong, to tracing it to the upstream change that caused it, to being warned before it reaches a decision at all. Stakeholders stop chasing corrections after the fact, and governance shifts from permissions held by a person to scoped agent identities and a record an auditor can analyze by pattern instead of incident by incident.
For anyone working with data, climbing the ladder pays off in leverage: at L1 your impact is capped by your hours; at L4 it is capped by how many agents you can supervise well - a far higher ceiling. The autonomy ladder also changes the economics of data departments: the cost of maintenance decreases dramatically, more time is available for identifying business opportunities based on data.
The dltHub context graph powers the control room
The leverage at the higher levels only works if everything the platform does is recorded. Grid equipment is allowed to act on its own because everything it does gets written down. This record makes it possible to rely on equipment nobody is watching. In dltHub that record is the context graph, the state layer of the platform and the live picture the control room works from: agents read it to act and write to it to record what they did, and humans read it to audit them.
The context graph maps every entity on the platform (sources, ingestion pipelines, transformations, datasets, jobs, alerts, agents, data apps), each carrying its own context: versioned code and configuration, schema, lineage, traces, quality checks, PII annotations. Every entity emits append-only, immutable events recording who or what acted and what it touched. And because dltHub sits in the path of the data at extract time, the pipelines emit this context themselves rather than scraping it from other systems after the fact.
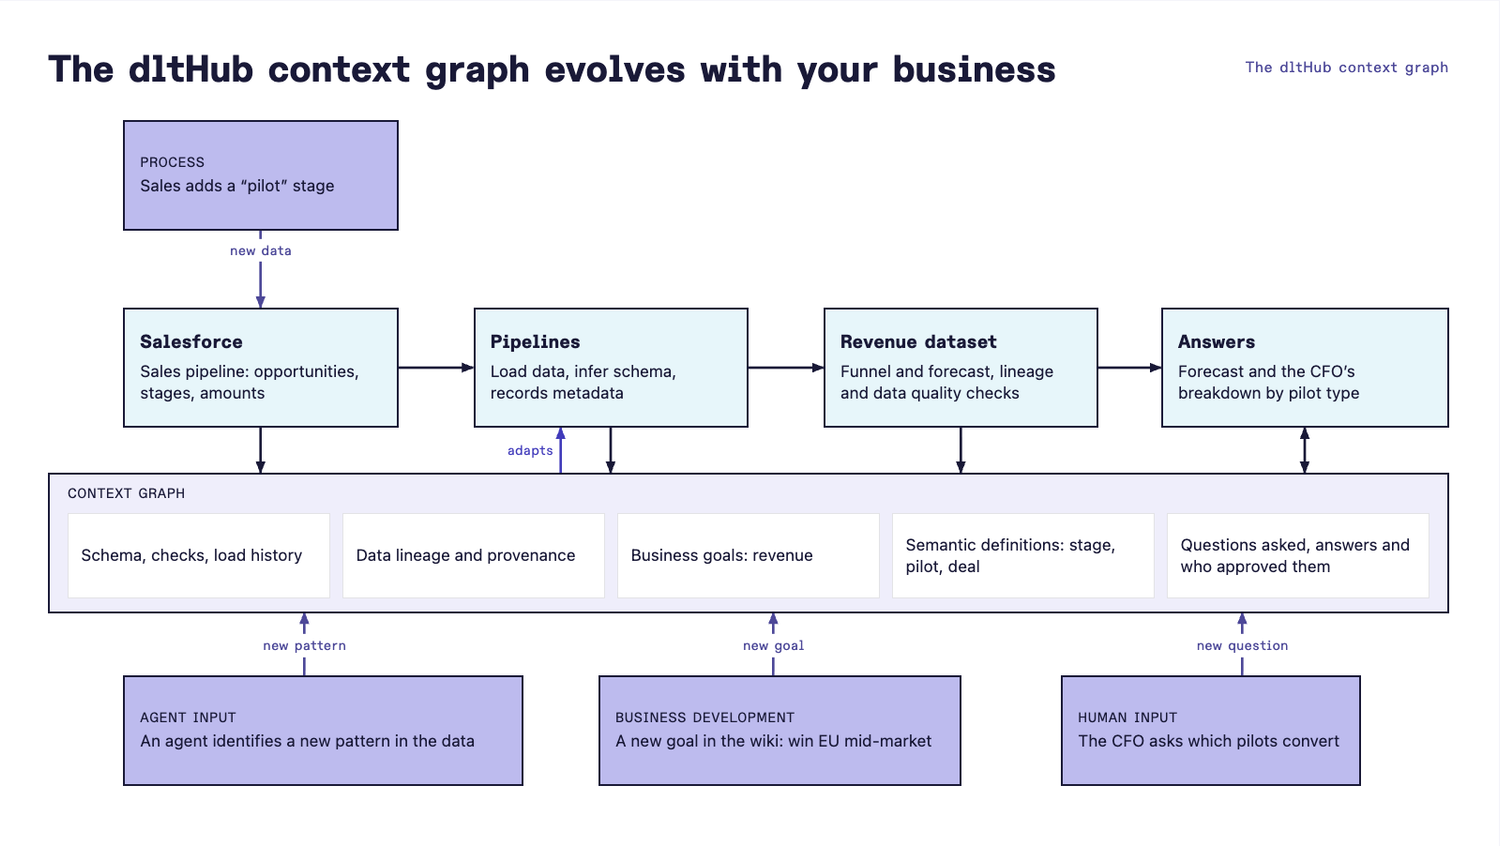
The graph tracks not only the platform but also the business. Sales adds a “pilot” stage in Salesforce and the new values arrive with the next load: the pipeline adapts to the schema change, and the revenue dataset carries the stage into the funnel and the forecast. Context also comes in from outside the pipelines: a question the CFO asks, a new goal the Chief of Staff writes in Notion, a pattern an agent finds in the data. All of it lands in the same graph, so the definition of “pilot” stays tied to how the company uses the word this quarter rather than to how someone defined it when the pipeline was built.
The graph is also what every autonomous action gets checked against. To automate an activity with an agent, it needs to answer five questions:
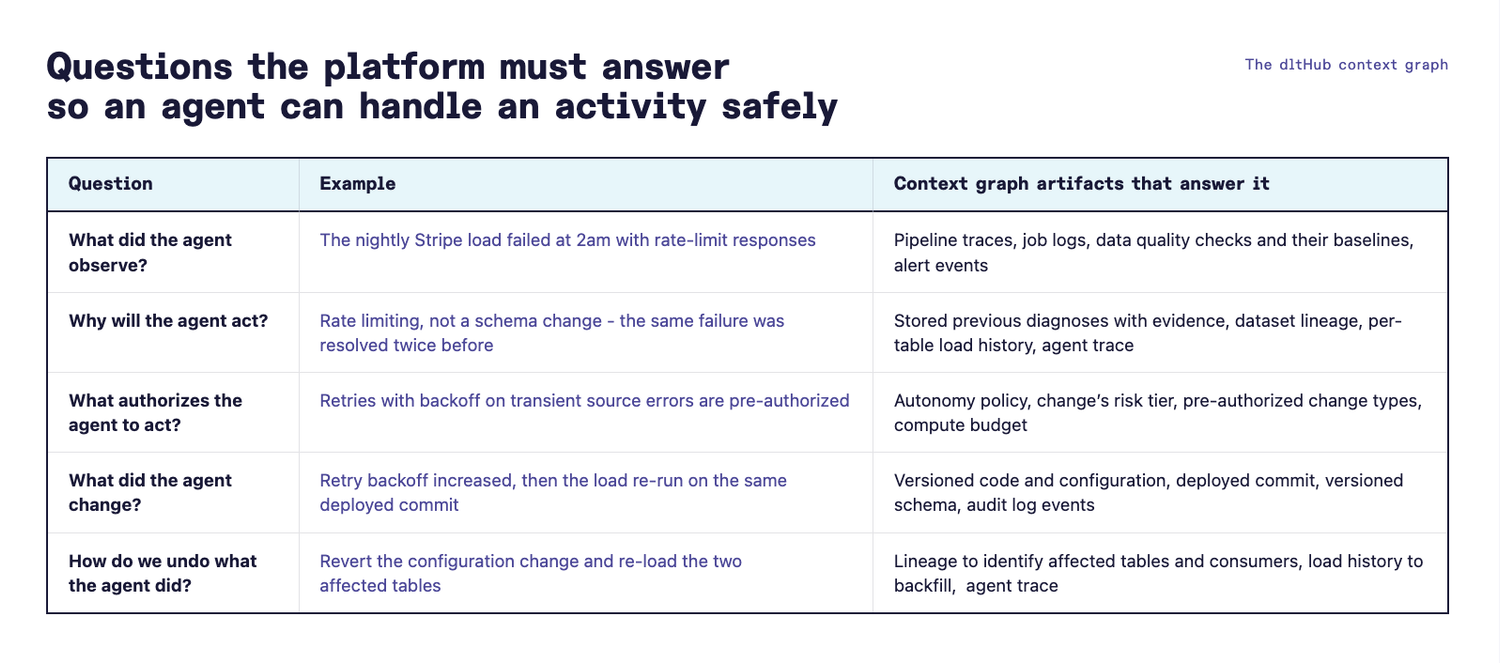
If any of these has no answer, the action stays with a human. Every decision to allow, deny or defer is written to the graph as a signed, immutable receipt naming the rule it matched and the outcome, for example an audit conducted months later. Agents and auditors read the same graph, so “who produced this number and who signed off” is a lookup. The Slack note in the introduction includes these answers: whatever agents did overnight, you can open the control room in the morning and see all of it.
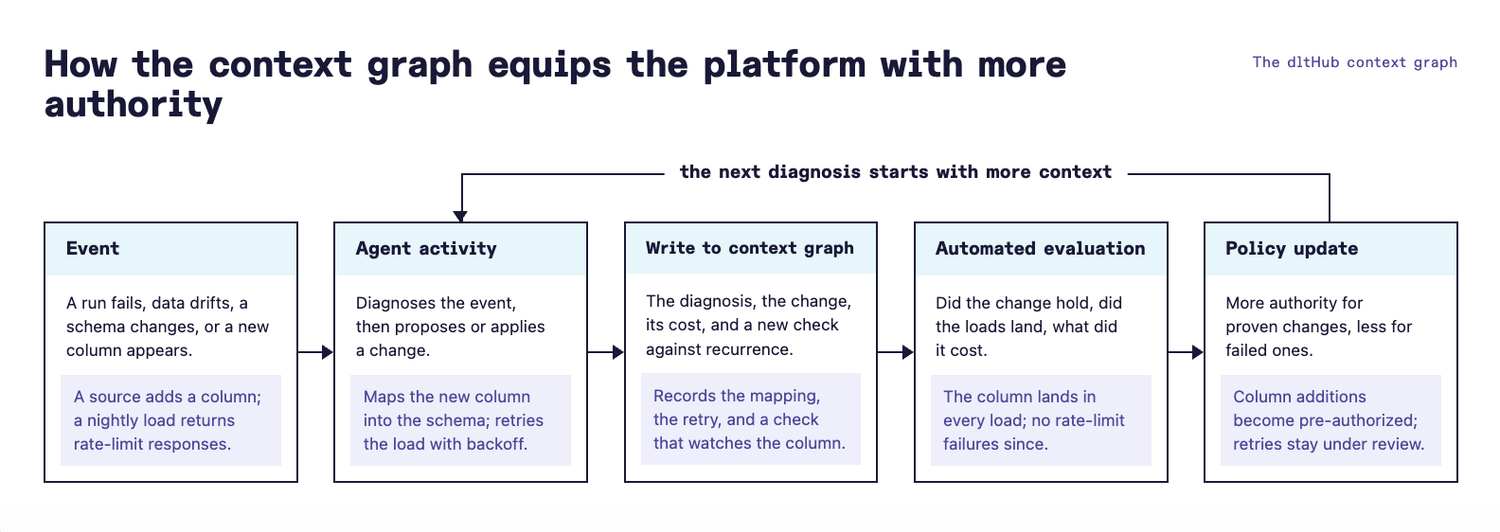
This is also why autonomy compounds. Every handled incident writes its diagnosis, fix, cost, and a new check back into the graph. Once a failure type has enough good outcomes, it moves from human review at L3 to pre-authorization at L4, which is how the agent in the intro got to fix the 2am failure on its own. Automated evaluations score every run against what actually happened and move agents up or down a level. The 10th failure costs less to handle than the first.
Where we are today and what's next
Today we are between L1 and L2 with dltHub: the AI harness is shipped, and most of L2's pieces exist and will soon be completed with our agent platform. Each level above has its infrastructure to earn, and we will climb one level at a time, with observability integrated in every step. Our roadmap shows what exists and how we close the gaps by 2027.
Go back to that Monday morning in the cafe. No firefighting - triage ran itself, the CFO ran their own investigation instead of filing a ticket in your queue, and the rest of the morning went into work that actually needs a data engineer: figuring out which data the company is missing, tightening contracts, deciding what to build next. You end up designing the platform and supervising its agents instead of chasing faults one line at a time.
With foundation models continuously evolving, we don't think the ladder ends at L4. Today the platform repairs what already exists, but the fee-breakdown story hints at the next step: a platform that notices which data would be worth having and proposes the pipeline before anyone asks for it, whether that data sits in a legacy system nobody wants to touch or in the nested traces of your own agents. Most companies have data like that fee breakdown sitting unused, in a payload nobody modelled or a system nobody had time to connect, because finding out whether it matters costs more than the question seems worth.
When we get there, it will be the same way we got everywhere else on the ladder, with a policy around it and transparency via the context graph. Our vision goes beyond automating an individual data engineer's job. We are building autonomous company infrastructure that many agents, systems and humans can build on. We're curious where you would draw the line: At which level is your team, and what prevents them from climbing the next step on the ladder?
Book a dltHub demo
See the AI Harness, team workspaces, and managed infrastructure running against your own sources.